Read this sentence once: The animal didn't cross the street because it was too tired. You knew immediately that "it" means the animal. Nothing in the grammar says so — "it" could just as easily point at the street. You resolved the ambiguity by holding the whole sentence in mind and weighing the words against each other.
That trick — comparing every word in a sequence to every other word, all at once — is the beating heart of a transformer model. The rest of the architecture exists to make that comparison cheap, stable, and repeatable at absurd scale.
Before Transformers, Words Moved Single File
Older sequence models, recurrent networks and their LSTM relatives, read text the way you read a receipt: one token at a time, carrying a running summary forward. That summary lived in a fixed-size vector. By word 400, the memory of word 3 had been overwritten many times.
Recurrent: word1 → [state] → word2 → [state] → word3 → [state] → ...
Transformer: word1, word2, word3 ... all compared simultaneously
Two problems followed. Long-range dependencies faded, so a pronoun 60 words after its noun became a coin flip. And because every step depended on the previous one, training could not be spread across a sequence in parallel — which kept the largest, most useful models out of reach.
Self-Attention: Every Word Looks at Every Other Word
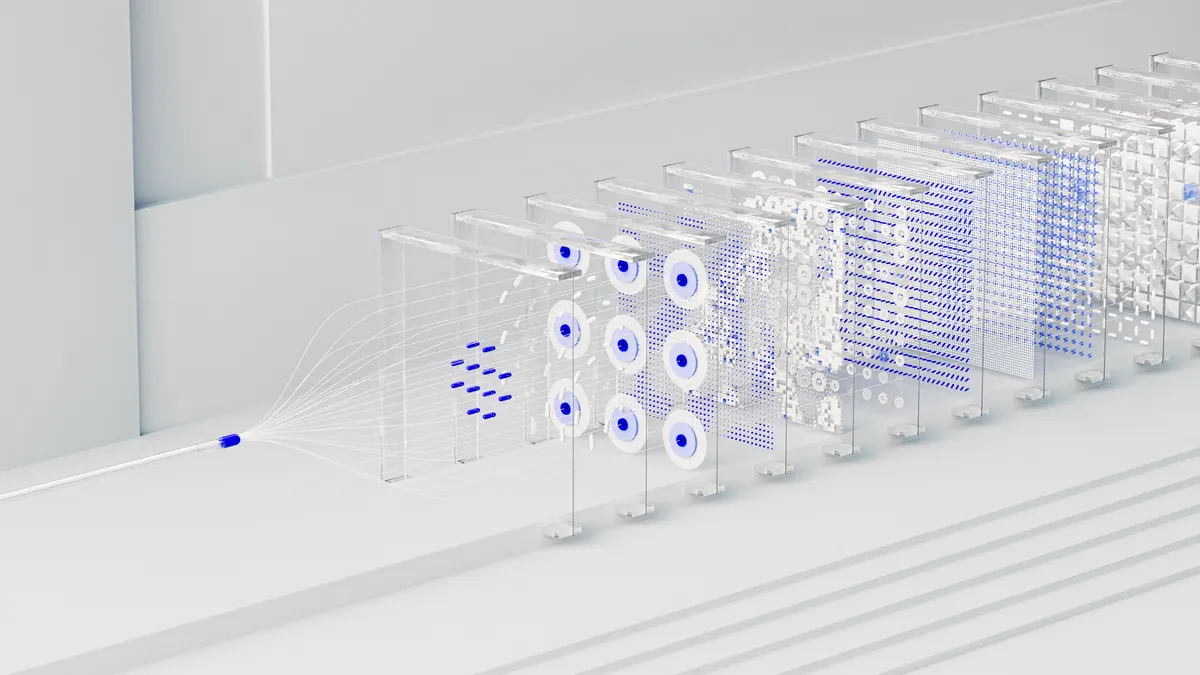
Self-attention throws out the single running summary. For each word, the model computes how much every other word should matter to it, then builds a blended representation from the whole sentence. The mechanism is built from three projections of each token:
- Query — what this word is looking for.
- Key — what this word offers, like the label on a book spine.
- Value — the content that actually travels if the match is good.
Each query is scored against every key. The scores are scaled so they stay in a workable range, then passed through a softmax so they become weights that sum to one. Multiply the values by those weights, add them up, and you have that word's output. In the animal sentence, "it" picks up a large weight on "animal" and a small one on "street."
Why multi-head attention matters
One attention pattern per word is thin. Transformers run several in parallel — the heads. Each head tends to specialise: one tracks who did what to whom, another pairs a verb with its object, another follows position or punctuation. The heads' outputs are concatenated, projected back into a single vector, and passed through a small feed-forward network that does per-word processing. Stack that block eight, thirty, or a hundred times and you have a deep transformer.
The Encoder–Decoder Skeleton
The original design has two halves. The encoder reads the input and produces contextual vectors for every token. The decoder generates output one token at a time; at each step it attends to what it has already written (masked self-attention, so it cannot peek ahead) and to the encoder's output through cross-attention.
Input tokens → [encoder stack] → contextual vectors → [decoder stack + cross-attention] → output tokens, one at a time
Attention itself has no sense of order, so positional information is added to the token embeddings before anything else happens. Without it, "dog bites man" and "man bites dog" would look identical to the model.
Three shapes you will meet
- Encoder-only — built for understanding: classification, search, tagging.
- Decoder-only — built for generation, one token at a time. Most conversational models today are this shape.
- Encoder–decoder — built for mapping one sequence to another, such as translation or summarisation.
Why Transformers Dominate
- They train in parallel. No step waits on the previous one, so large batches and large models are practical.
- They scale steadily. Across many tasks, adding parameters and data has kept improving results rather than flattening out quickly.
- They are flexible. Attention does not care whether the tokens come from text, audio frames, or image patches — one architecture covers all of them.
- They transfer well. Pretrain once on broad data, then fine-tune or prompt for a specific job, and you skip most of the labelled-data problem.
Where They Still Struggle
Attention compares every pair of tokens, so cost grows with the square of sequence length. Doubling the context does not double the compute — it roughly quadruples it. That is why long-context models are expensive, and why so much work goes into cheaper approximations.
Transformers also have no memory between calls. Whatever the model knows about your project has to be inside the prompt or baked into the weights during training. And fluency is not accuracy: the model optimises for plausible next tokens, so a confident-sounding sentence can still be wrong. Treat generated facts as leads to verify, not as sources.
A Practical Path to Understanding Them
Reading about attention is not the same as watching it work. Try this sequence over a weekend:
- Run a tokenizer on a paragraph you wrote. Look at how it splits unusual words — that is the model's actual input.
- Load a small open model and print the attention weights for one sentence. You will see the diagonal pattern and the long-range links.
- Change one word and watch the weights move. This makes the query–key idea concrete fast.
- Count parameters in each layer. The feed-forward blocks usually dominate — attention is not always where the bulk of the weights lives.
- Write down the shape of every tensor as it flows through the block. Getting shapes right is most of the battle when reading code.
Do that once and phrases like "self-attention" and "encoder–decoder" stop being jargon. They become a shape you can picture, and a mechanism you can reason about the next time a model surprises you.
Photo: Google DeepMind / Pexels